Introduction
Cloud-Native Integration has revolutionized how organizations build and deploy AI applications in today's fast-paced digital landscape. As businesses increasingly adopt artificial intelligence to drive innovation, the need for scalable, resilient, and efficient deployment strategies has become paramount.
This guide explores the complete journey from conceptualizing AI applications to successfully deploying them in cloud-native environments — ensuring your development teams can leverage modern infrastructure patterns while maintaining security, performance, and cost-effectiveness throughout the entire lifecycle.
Microservices Architecture
Break down AI applications into independent, scalable services for better resource management and faster deployment cycles.
Container Orchestration
Leverage Kubernetes to ensure consistent AI-app deployment across development, staging, and production environments.
CI/CD Automation
Implement robust pipelines that accelerate AI model deployment while maintaining quality through automated testing.
Infrastructure as Code
Adopt declarative infrastructure management for reproducible, version-controlled cloud environments.
Understanding Cloud-Native Architecture for AI Applications
Cloud-native architecture provides the foundation for building scalable AI applications that can adapt to changing business needs. By leveraging containerization, microservices patterns, and declarative APIs, development teams can create AI solutions that scale horizontally, recover from failures automatically, and utilize compute resources efficiently.
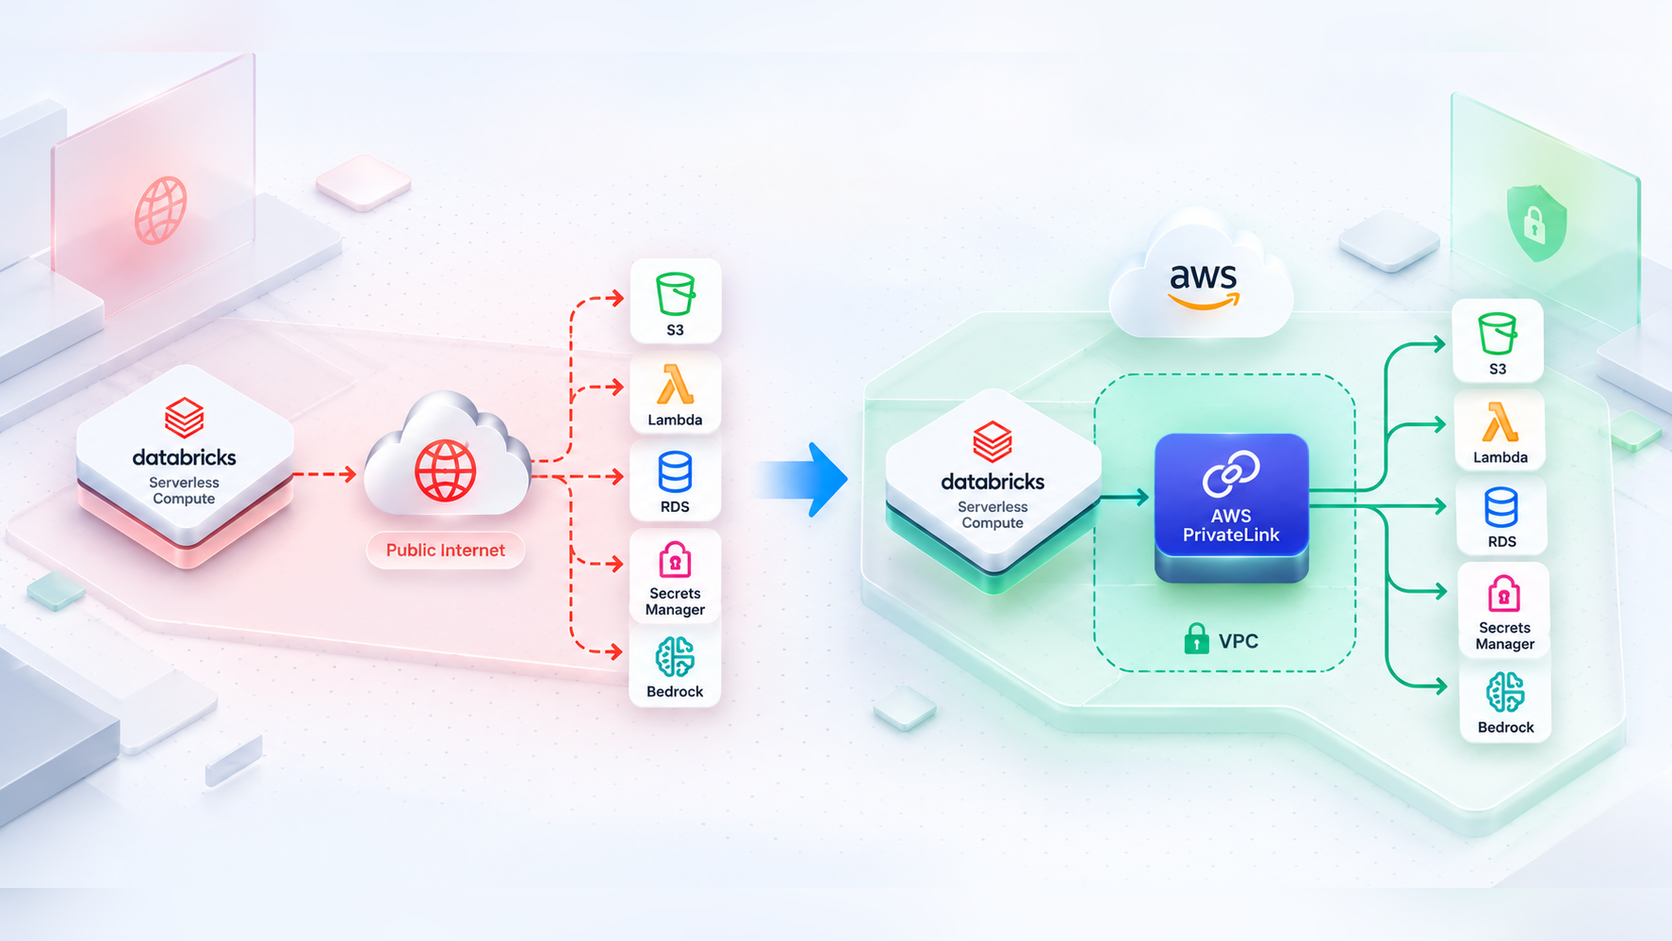
The adoption of cloud-native patterns facilitates seamless integration with existing enterprise systems. Organizations can connect AI services to databases, message queues, and external APIs while maintaining loose coupling — ensuring teams can update or scale individual services without affecting the entire ecosystem.
Essential Components of AI-App Development Pipeline
Data Pipeline
Collect, cleanse, and prepare training data through ETL processes that aggregate from various sources, apply feature engineering, and store processed datasets using streaming and batch processing frameworks.
Model Development & Training
Version control for code and models, experiment tracking, and automated retraining workflows. Self-service capabilities including managed notebooks, GPU clusters, and model registry systems.
Deployment & Serving
Package models into containers, implement API endpoints, and establish monitoring for accuracy degradation. Deploy using blue-green or canary strategies, minimizing risk while enabling rapid rollbacks.
Implementing Microservices Patterns for AI Applications
Microservices architecture offers significant advantages by decomposing complex systems into smaller services that communicate through well-defined interfaces. This enables independent scaling of compute-intensive inference services while keeping lightweight orchestration services on minimal resources.
When implementing microservices for AI applications, design services around business capabilities rather than technical layers. A recommendation system might include separate services for user profiling, content similarity, model inference, and result ranking — each maintaining its own data store and exposing RESTful or gRPC endpoints.
Container orchestration platforms like Kubernetes provide the runtime environment. Teams define resource requirements, health checks, and scaling policies through declarative configurations — automatically scheduling containers, restarting failed services, and performing rolling updates without downtime.
Cloud-Native Integration Strategies for Seamless Deployment
Infrastructure as Code (IaC)
Tools like Terraform or AWS CloudFormation define cloud resources through version-controlled files — ensuring reproducible environments, facilitating peer review, and enabling automated provisioning.
GitOps
Use Git repositories as the source of truth for application and infrastructure definitions. Tools like ArgoCD continuously reconcile desired state with actual cluster state, providing clear audit trails and simplified rollbacks.
Secure CI/CD Pipelines
Integrate security scanning and automated testing throughout deployment. Validate model performance, check for data drift, and ensure predictions meet accuracy thresholds before promotion.
Golden Path Patterns
Standardized deployment templates for common AI architectures that incorporate best practices while allowing customization — accelerating time-to-production while maintaining consistency.
Key Technologies and Tools
Container Technologies
Docker & Podman — standardized packaging ensuring consistency across environments, bundling code, dependencies, and ML frameworks.
Orchestration Platforms
Kubernetes with KubeFlow extensions for distributed training and model serving. Managed services like Amazon EKS or Google GKE reduce operational overhead.
Service Mesh
Istio or Linkerd for traffic management, security policies, and observability — enabling canary releases and A/B testing without code changes.
Observability Stack
Prometheus for metrics, Grafana for visualization, Jaeger for tracing — comprehensive insights to identify bottlenecks and monitor resource utilization.
MLOps Platforms
MLflow, Kubeflow, or Amazon SageMaker for experiment tracking, model registry, and deployment orchestration.
"Over 78% of organizations use Kubernetes in production, with AI workloads representing one of the fastest-growing use cases."
— CNCF Survey
Best Practices for Production-Ready AI Deployments
Model Versioning & Governance
Track training data, hyperparameters, code versions, and evaluation metrics. Establish governance processes requiring stakeholder approval before production promotion.
Performance Monitoring & Alerting
Monitor technical metrics (latency, throughput, error rates) and business metrics (prediction accuracy). Track data drift and concept drift to identify when models need retraining.
Resource Optimization
Right-size compute resources based on actual workload. Use horizontal pod autoscaling and consider spot instances for batch training to reduce costs by up to 80%.
Security Hardening
Implement network policies, use secrets management like HashiCorp Vault, apply least privilege, and regularly scan container images for vulnerabilities.
Disaster Recovery Planning
Design with fault tolerance using circuit breakers and graceful degradation. Maintain backup models for failover and implement geographic redundancy for critical services.
Continuous Model Improvement
Establish feedback loops capturing prediction results and business outcomes. Implement A/B testing frameworks and use online learning or periodic retraining to adapt to changing data distributions.
Conclusion
Successful AI-app development requires a thoughtful approach to cloud-native integration that balances innovation with operational excellence. By adopting microservices architectures, implementing robust CI/CD pipelines, and leveraging modern orchestration platforms, organizations can build AI applications that scale efficiently while maintaining reliability and security.
Ready to transform your AI development practices? Contact our team to discuss how our expertise in cloud-native integration and AI services can accelerate your journey from idea to production deployment.