How a model-checkpoint update can turn into a measurable inference improvement
A practical engineering story: the bottleneck, the benchmark, the code, and the rollout.
Introduction
The new model checkpoint delivers approximately 2.3× faster inference for our benchmark workload.
When a workflow feels slow, the first instinct can be to add compute or redesign the surrounding service. We wanted to avoid changing infrastructure before understanding the bottleneck. So we started with a narrower question: how much time was ai_extract spending in model inference, and could the checkpoint itself be improved?
We compared the previous checkpoint with a new checkpoint and observed an approximately 2.3× inference speedup on our benchmark workload. That is the result from this comparison; it should not be read as a guarantee that every input, device, or production deployment will see the same improvement.
The important part of the story is what stayed stable. The application-facing extraction workflow did not need a broad redesign; the main change was the checkpoint used beneath it. That gave us a focused change to evaluate instead of changing several parts of the system at once.
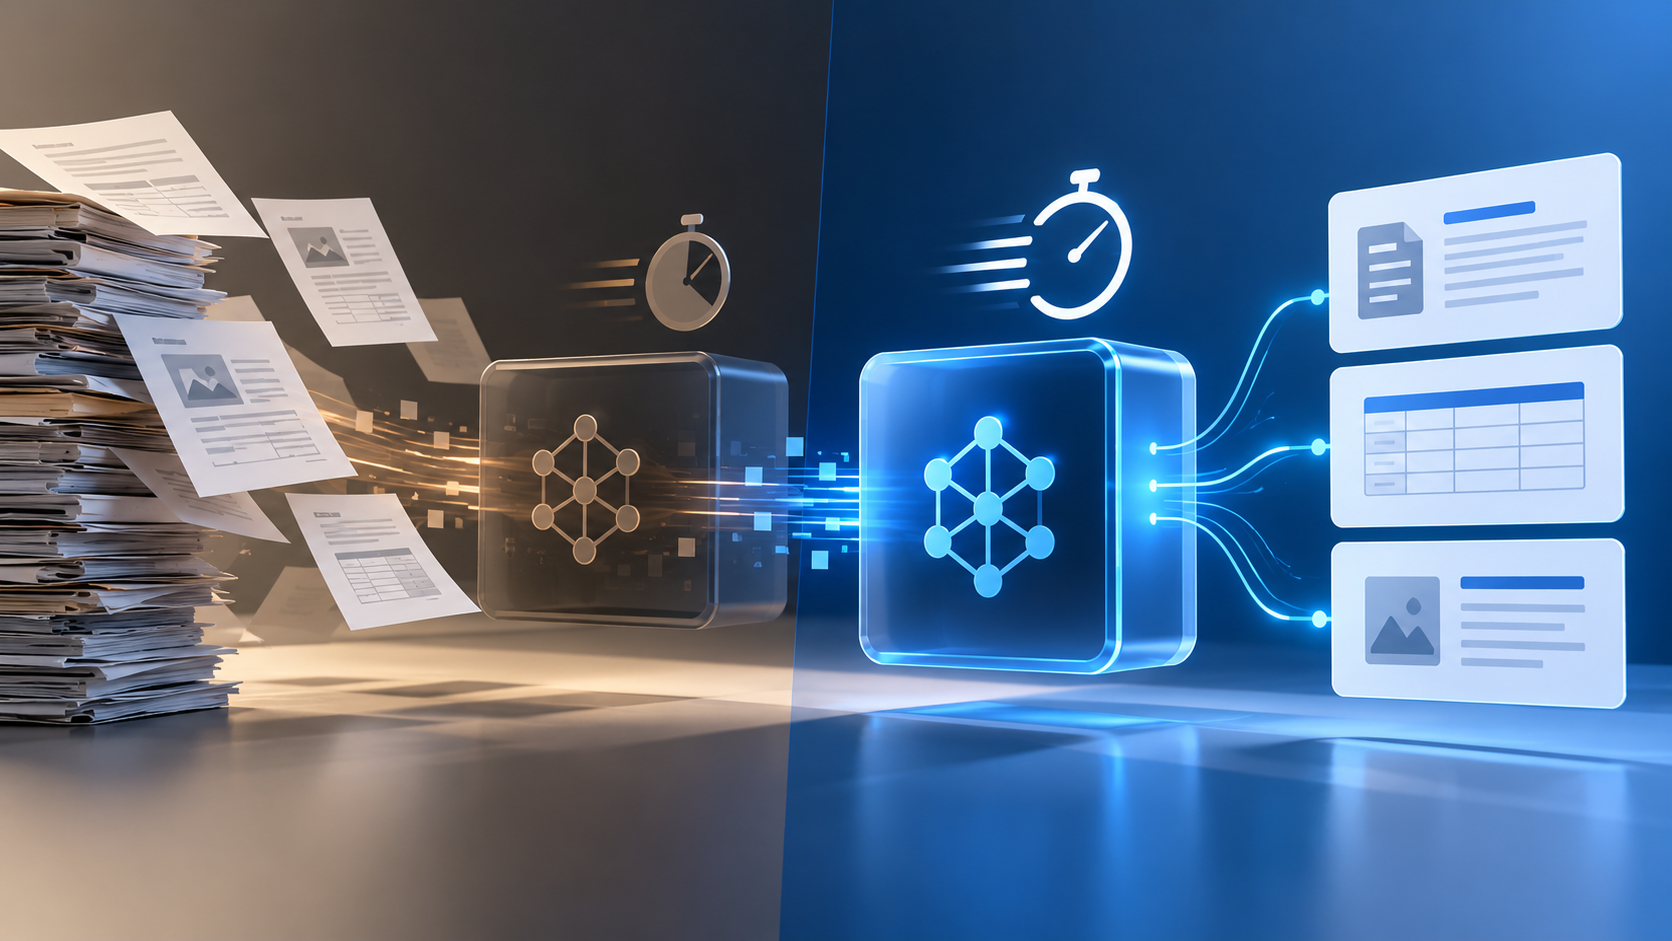
Figure 1: ai_extract Before and After the Model Checkpoint Change
Same benchmark workload
Same application interface
BEFORE = Previous
NOW = New
Same extraction workflow
Old and new checkpoints evaluated on a strictly comparable extraction workload.
Warm up the inference run thoroughly before taking measurements to avoid cold-start bias.
Repeated inference runs with median aggregation instead of relying on a single volatile result.
Calculate the direct ratio of old median latency to new median latency under equivalent environments.
2.3× faster model inference does not automatically mean 2.3× faster end-to-end requests. Pipeline stages like preprocessing, networking, and storage remain outside the checkpoint timing boundary.
The Problem We Wanted to Solve
A model can produce useful results and still become a bottleneck if the surrounding workflow has to wait too long for them. For an extraction system, latency sits alongside quality, reliability, and cost as a production concern. We needed to identify which stage deserved attention before committing to a larger infrastructure change.
Instead of choosing a solution first, we treated this as a measurement problem: where is the time being spent? If model inference is the bottleneck, adding capacity around it may not be the most direct fix.
We considered the extraction path as a sequence of stages: input preparation, model inference, post-processing, and the services between them. Keeping those stages conceptually separate helps avoid a common mistake: treating a model-level improvement as if it were automatically the same improvement for the complete request. The specific change in this comparison was the model checkpoint.
Before: The Previous Checkpoint
Before the change, ai_extract used the previous checkpoint. The caller-facing operation can be represented simply as:
result = ai_extract(document)This separation matters because callers should depend on the extraction interface, not on the identity of the checkpoint behind it. With that boundary in place, we could evaluate a different checkpoint without requiring every caller to know about the model change.
What Changed
We changed the checkpoint used for the extraction workload and kept the surrounding application flow essentially the same. This is a deliberately narrow comparison: by limiting the main change, we can more clearly evaluate the relationship between the checkpoint replacement and the observed inference result. A controlled benchmark is still necessary to rule out differences in inputs, hardware, runtime settings, or measurement method.
The application can continue to call ai_extract(document) while the implementation selects the new checkpoint underneath. A stable interface makes checkpoint changes easier to test and roll back, and keeps model-specific details from spreading through the application.
Before vs Now
The evaluation isolates the model checkpoint beneath the contract. The application layer and interface remained identical:
| Area | Before | Now |
|---|---|---|
| Extraction workflow | Same | Same |
| Application interface | Same | Same |
| Model checkpoint | Previous | New |
| Inference performance | Baseline | ≈ 2.3× faster |
| Application redesign | Not required | Not required |
How We Measured the Improvement
A speedup number is only as trustworthy as the comparison behind it. The old and new checkpoints should receive the same representative workload under the same hardware, batch size, precision, runtime, and preprocessing conditions. Otherwise, a change in the test setup could be mistaken for a checkpoint improvement.
For a useful comparison, we warm up the model, run repeated measurements, and compare latency for the old and new inference call using the same inputs. The example below is a PyTorch benchmark template, not a claim that it is the exact code used to obtain the reported 2.3× result. It measures the inference callable only; it does not include tokenization, file I/O, network calls, or other pipeline stages unless those are deliberately included in the callable. CUDA synchronization is included because GPU work can execute asynchronously.
import statistics
import time
import torch

def benchmark_inference(infer_once, *, device, warmup=20, repeats=7, iterations=100):
    """
    infer_once: zero-argument callable that runs exactly one model inference.
    device: torch.device matching the model/input device.
    Returns median latency per inference in seconds.
    """
    if warmup < 0 or repeats < 1 or iterations < 1:
        raise ValueError("warmup must be >= 0; repeats and iterations must be >= 1")

    def synchronize():
        if device.type == "cuda":
            torch.cuda.synchronize(device)

    # Load both checkpoints and prepare identical inputs before timing.
    # Put each model and its inputs on the same device, and call model.eval().
    with torch.inference_mode():
        for _ in range(warmup):
            infer_once()

        timings = []
        for _ in range(repeats):
            synchronize()
            start = time.perf_counter()
            for _ in range(iterations):
                infer_once()
            synchronize()
            timings.append((time.perf_counter() - start) / iterations)

    return statistics.median(timings)

# Implement these wrappers using your project's real model/ai_extract API.
# Each wrapper must run one inference with the same prepared input.
old_latency = benchmark_inference(old_infer_once, device=device)
new_latency = benchmark_inference(new_infer_once, device=device)

if new_latency <= 0:
    raise ValueError("New latency must be positive")

speedup = old_latency / new_latency
print(f"Old median latency: {old_latency * 1000:.2f} ms")
print(f"New median latency: {new_latency * 1000:.2f} ms")
print(f"Inference speedup: {speedup:.2f}x")This is a PyTorch template, not drop-in code for an unknown ai_extract implementation. Define old_infer_once and new_infer_once with the project's real inference API; load both checkpoints and prepare identical inputs before timing; put both models and inputs on the same target device; and call eval() on both models.
The timed region intentionally excludes preprocessing, I/O, networking, and post-processing unless the wrapper includes them. If ai_extract is not implemented in PyTorch, use the framework's recommended benchmarking tools instead. Do not publish the 2.3× claim from this example alone: the team's actual benchmark logs are the evidence.
What Does 2.3× Faster Mean?
We express the result as a ratio of old latency to new latency:
Speedup = Old inference latency / New inference latency
For illustration only, a decrease from 2.3 seconds to 1.0 second would equal a 2.3× speedup (2.3 ÷ 1.0 = 2.3). These values are examples, not measurements from our system. For a publishable benchmark, report the actual old and new latency values and describe the tested workload and runtime conditions.
Why the Improvement Matters
If this result holds for representative production traffic, faster inference could reduce the time spent waiting for the model and might increase throughput on the same infrastructure. The size of that benefit depends on the rest of the system and on whether inference is the dominant bottleneck.
Downstream stages may also receive results sooner. That is a plausible benefit, but a model-only benchmark does not establish the size of the end-to-end improvement.
The distinction is important: the reported 2.3× figure is a model-inference result for the benchmark workload. It does not, by itself, mean the complete application is 2.3× faster.
Model Speedup vs End-to-End Speedup
A real request involves more than a model forward pass. Preprocessing, queueing, network calls, storage, post-processing, and other services all contribute to total latency. If those stages account for much of the request time, a large improvement in model inference can translate into a much smaller end-to-end gain.
We therefore keep the claims separate: our benchmark showed approximately 2.3× faster model inference, while the end-to-end application impact remains to be measured. The next step is to time the complete workflow rather than infer its performance from the model result alone.
What We Learned
Measure before optimizing
Locate the bottleneck before assuming that more infrastructure is the answer.
Checkpoint as production decision
Alongside quality, a checkpoint can affect latency, throughput, memory use, compute utilization, scalability, and cost.
Keep logic behind a stable interface
A stable ai_extract() boundary makes it easier to compare checkpoints, replace one, or roll back without spreading model-specific details throughout the application.
What We Want to Measure Next
The 2.3× result is a useful milestone, but it is only one part of the performance picture. Next, we should measure end-to-end p50/p95/p99 latency, throughput, CPU/GPU and memory utilization, cost, and extraction quality under representative traffic.
Our Point of View
The headline number is useful, but the more durable lesson is the process behind it: measure first, identify the layer that needs attention, change one main variable, and test again. Here, we changed the checkpoint and observed approximately 2.3× faster inference on our benchmark workload without a broad application redesign.
The sequence is straightforward but worth preserving: measure the baseline, identify the bottleneck, change one main variable, repeat the benchmark, and then measure the complete request.
Conclusion
We replaced the checkpoint behind ai_extract and observed approximately 2.3× faster inference on our benchmark workload while keeping the application-facing extraction workflow the same. This is a model-level result, not proof of a 2.3× end-to-end speedup.
The next step is to reproduce the benchmark with documented settings and then test representative production-like inputs. Measuring end-to-end latency, throughput, resource utilization, cost, and extraction quality will show how much of the model-level gain translates into a real system-level benefit.
References
The references below provide background on inference optimization and benchmarking methodology. They do not establish the 2.3× result itself; that figure is based on the internal ai_extract benchmark.
The published 2.3× figure should be supported by the team's actual benchmark output, including measured old/new latency values, hardware/runtime configuration, workload definition, and benchmark iterations.