Why Real-Time Data Matters
Modern businesses need instant insights and always-fresh data to make faster decisions, personalize experiences, automate operations, and deliver real-time AI.
Faster Decisions
React to events as they happen and drive immediate impact.
Better Experiences
Power personalization, recommendations and live interactions.
Operational Efficiency
Automate data flows and reduce manual refresh cycles.
AI-Ready Data
Deliver fresh, high-quality data for AI, ML and advanced analytics.
What is Delta Live Tables?
Delta Live Tables (DLT) is a declarative framework for building reliable, maintainable and scalable data pipelines. It simplifies complex data engineering tasks so teams can focus on delivering business value.
Core capabilities
- Declarative pipeline development
- Automatic data quality and validation
- Scalable stream & batch processing
- Built on Delta Lake reliability
- Integrated with Unity Catalog
Declarative Data Pipeline Architecture
Integrated stream & batch processing engine with automated quality controls and enterprise governance.
Delta Live Tables (DLT)
● LIVE RUNTIMEStreaming & Batch Processing Engine
Declarative Pipelines
Focus on business logic while DLT automatically builds execution DAGs and manages dependencies.
Automatic Data Quality
Define data expectations once to automatically detect bad data, track metrics, and prevent bad data propagation.
Delta Lake Reliability
Built on Delta Lake for ACID transactions, schema enforcement, time travel, and high performance querying.
Unity Catalog Governance
Integrated with Unity Catalog for fine-grained access control, automated data lineage, and audit logs.
Inside a Delta Live Tables Pipeline
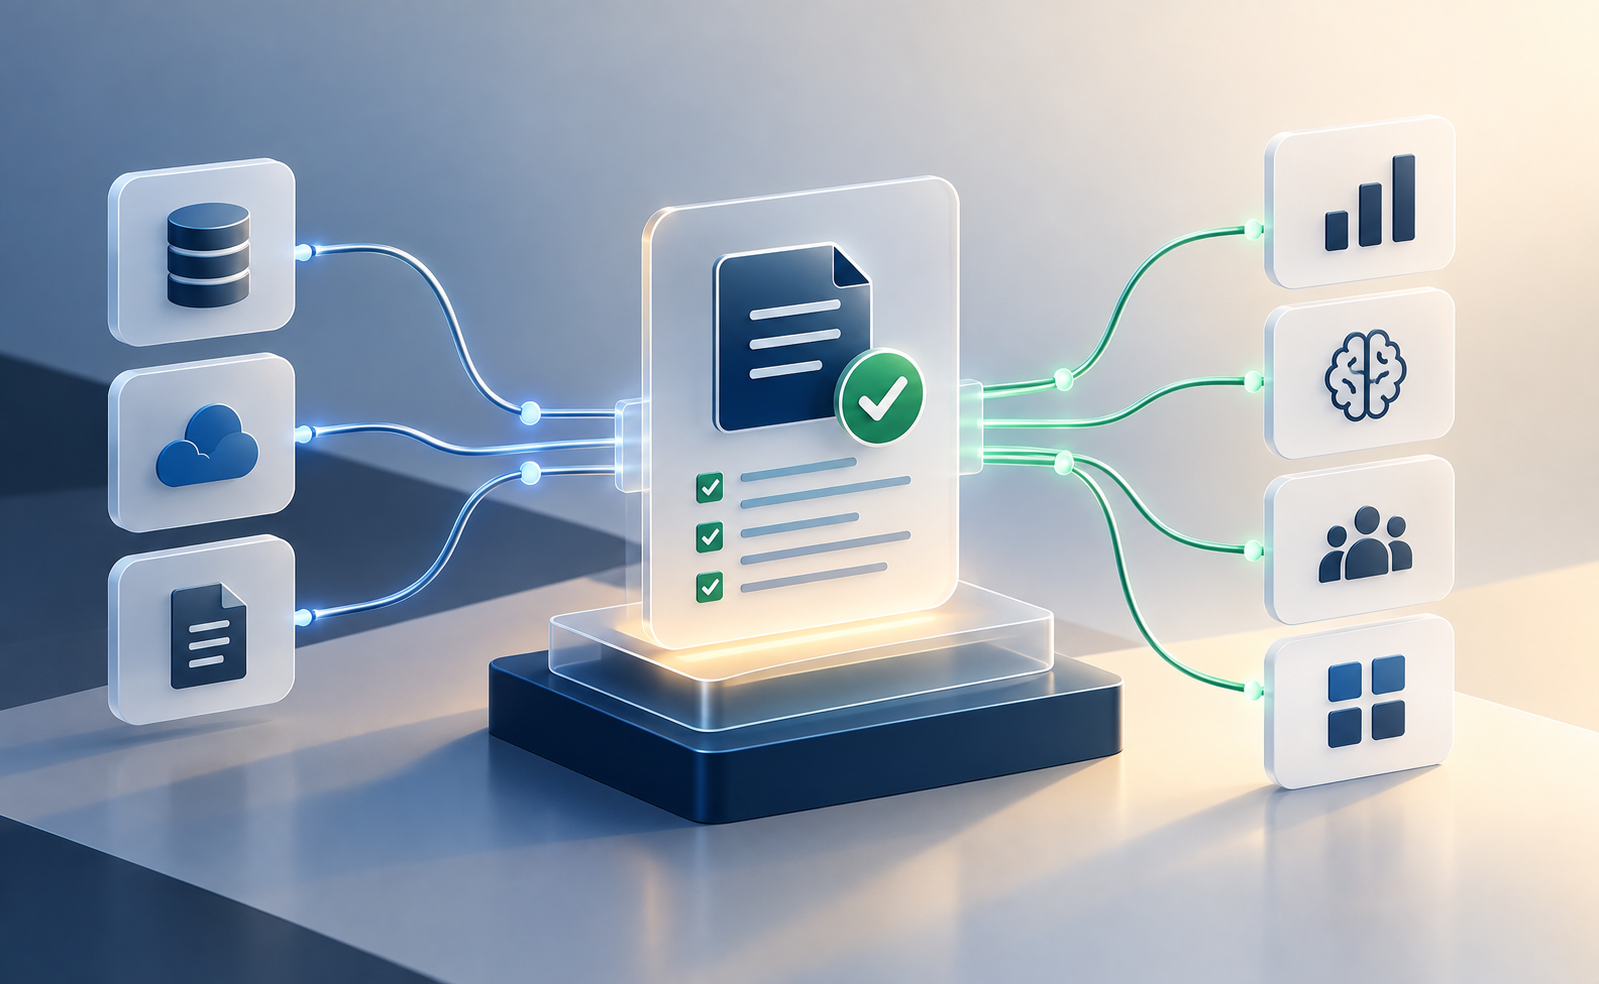
A typical real-time pipeline turns raw events into trusted, governed data through repeatable stages.
Bring in streaming and batch sources such as:
Apply transformations with declarative pipelines and built-in fault tolerance.
Validate data, store trusted Delta tables, then serve analytics and AI workloads.
Key DLT Benefits
Less Code, More Value
Focus on logic, not infrastructure.
Monitoring & Alerts
Built-in metrics, lineage and alerting.
High Reliability
Automatic retries, backfills and data recovery.
Cost Efficient
Serverless options to optimize cost and performance.
Traditional Approach vs DLT
Ideal for Every Use Case
DLT can support multiple real-time data workloads.
“DLT helps us build reliable pipelines faster, ensuring our data is always fresh, trusted and ready for analytics and AI.”
- Abilytics Data Engineering Practice
End-to-End Real-Time Data Architecture with DLT
Data moves from source systems through ingestion, transformation, quality, orchestration, governance and serving layers.
Left-to-Right End-to-End Pipeline
Streaming / Batch
Kafka, CDC, APIs, Files, Databases
Declarative Processing
Support for Streaming & Batch
Validation & Unity Catalog
Automated data-quality validation & expectations
End Users & Applications
Analytics, Dashboards, ML, AI applications
Build on a Modern Data Foundation
A strong DLT implementation connects every layer.
Foundation Stack (Bottom → Top)
Applications
Trusted data reaches dashboards, ML and AI.
Data Pipelines
Declarative processing for streaming and batch.
Delta Lake
Reliable storage with ACID transactions.
Cloud Infrastructure
Scalable, secure and cost optimized.
Why Databricks Delta Live Tables?
Faster Time to Value
Build and deploy pipelines in minutes, not weeks.
Scalable & Elastic
Handle growing data volumes without operational hassle.
Automatic Data Quality
Define expectations once and DLT enforces them.
Built for AI Era
Deliver trusted, real-time data for AI and ML.
Unified Platform
Ingest, transform, govern and serve in one platform.
Open & Interoperable
Built on open formats and industry standards.
Talk to Our Experts
Build real-time. Deliver impact. Power AI.
Abilytics helps enterprises build modern, real-time data platforms with Databricks.