Unify ingestion, transformation and orchestration on a single platform. Build reliable, scalable and cost-efficient pipelines with Databricks Lakeflow.
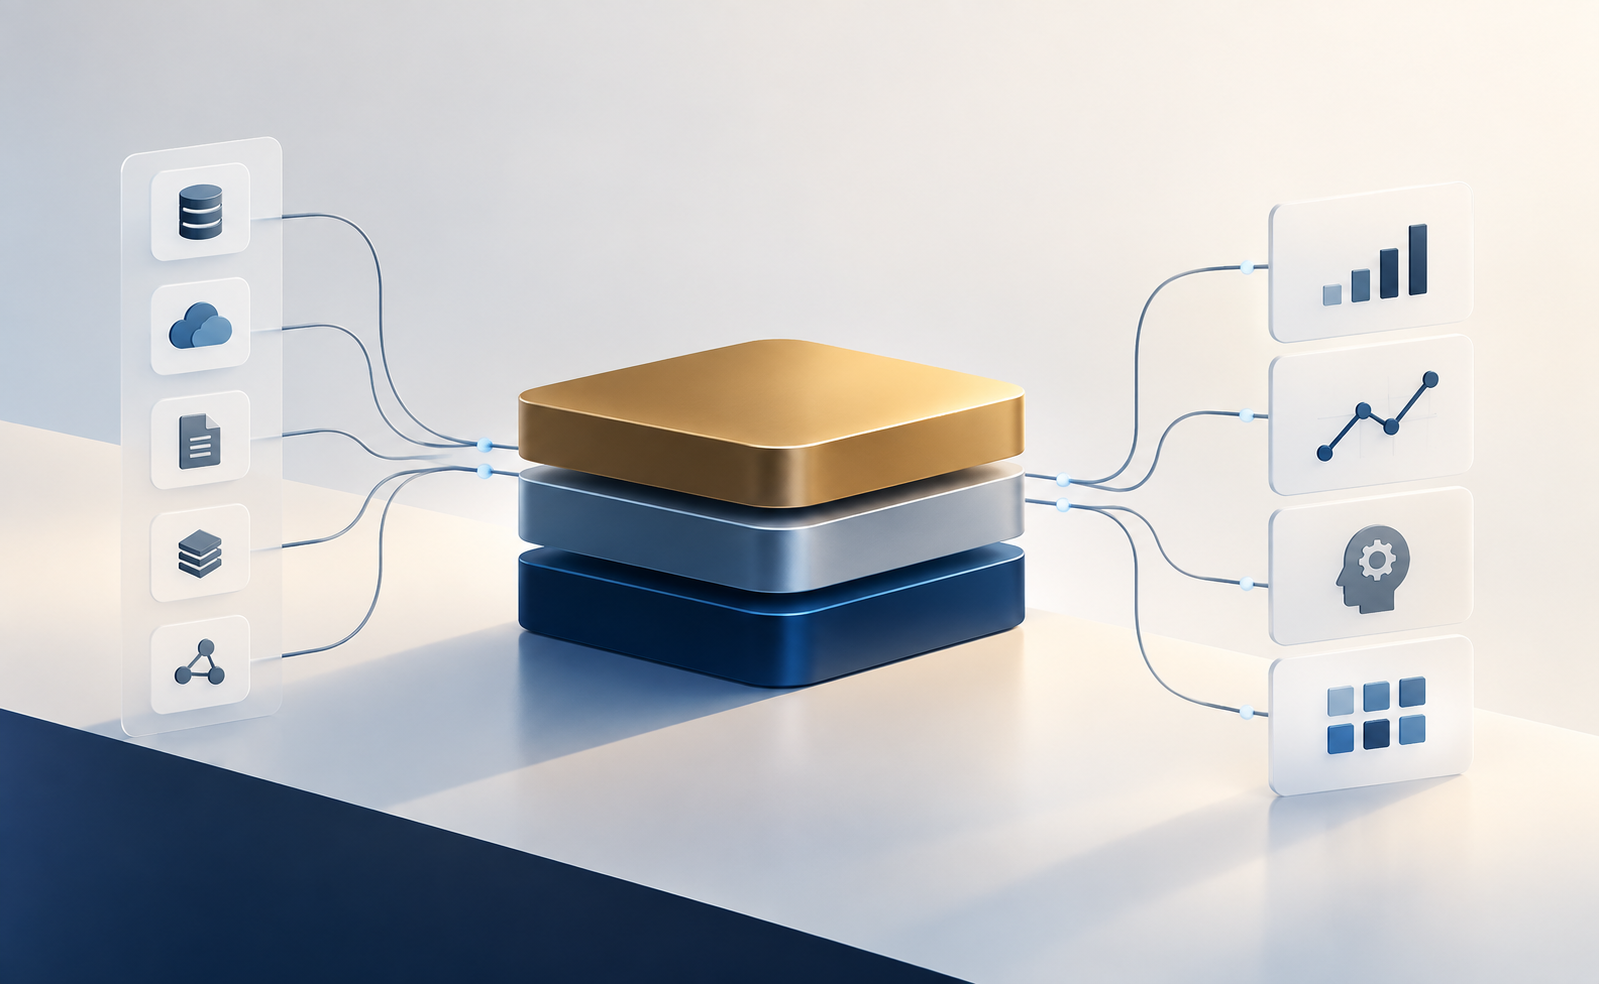
The Data Stack, Simplified
Lakeflow brings ingestion, transformation and orchestration into a unified experience - so teams can focus on building data products instead of managing infrastructure.
Data Sources
Databases, SaaS, APIs, Files, Streams
Lakeflow Connect
Managed & Standard Connectors
Lakeflow Pipelines
Batch & Streaming Transformations
Lakeflow Jobs
Orchestration, Scheduling and Monitoring
Analytics & AI
Dashboards, ML, RAG & AI Apps
Why Real-Time Data Matters
Modern businesses need instant insights and always-fresh data to make faster decisions, personalize experiences, automate operations, and deliver real-time AI.
Faster Decisions
React to events as they happen and drive immediate impact.
Better Experiences
Power personalization, recommendations and live interactions.
Operational Efficiency
Automate data flows and reduce manual refresh cycles.
AI-Ready Data
Deliver fresh, high-quality data for AI, ML and advanced analytics.
Why Lakeflow?
Unified Experience
Ingestion, pipelines and orchestration - all in one platform.
Serverless by Design
Dedicated serverless compute that auto-scales your workload.
Built for the Lakehouse
Tightly integrated with Delta Lake and Unity Catalog.
AI-Ready Pipelines
Deliver trusted data for analytics, ML and AI applications.
Inside a Lakeflow Pipeline
A typical pipeline follows the medallion architecture and is fully orchestrated end-to-end.
Connect to any source and ingest data incrementally.
Validate, clean and enrich data with quality checks.
Organize Bronze, Silver and Gold layers for trusted consumption.
Publish to dashboards, ML models, RAG systems and AI applications.
Serverless Advantage
No cluster management
Focus on pipeline logic instead of infrastructure.
Auto scaling & optimization
Compute adapts to workload demand.
Pay for usage
Reduce idle infrastructure overhead.
Built-in high availability
Increase resilience for production workloads.
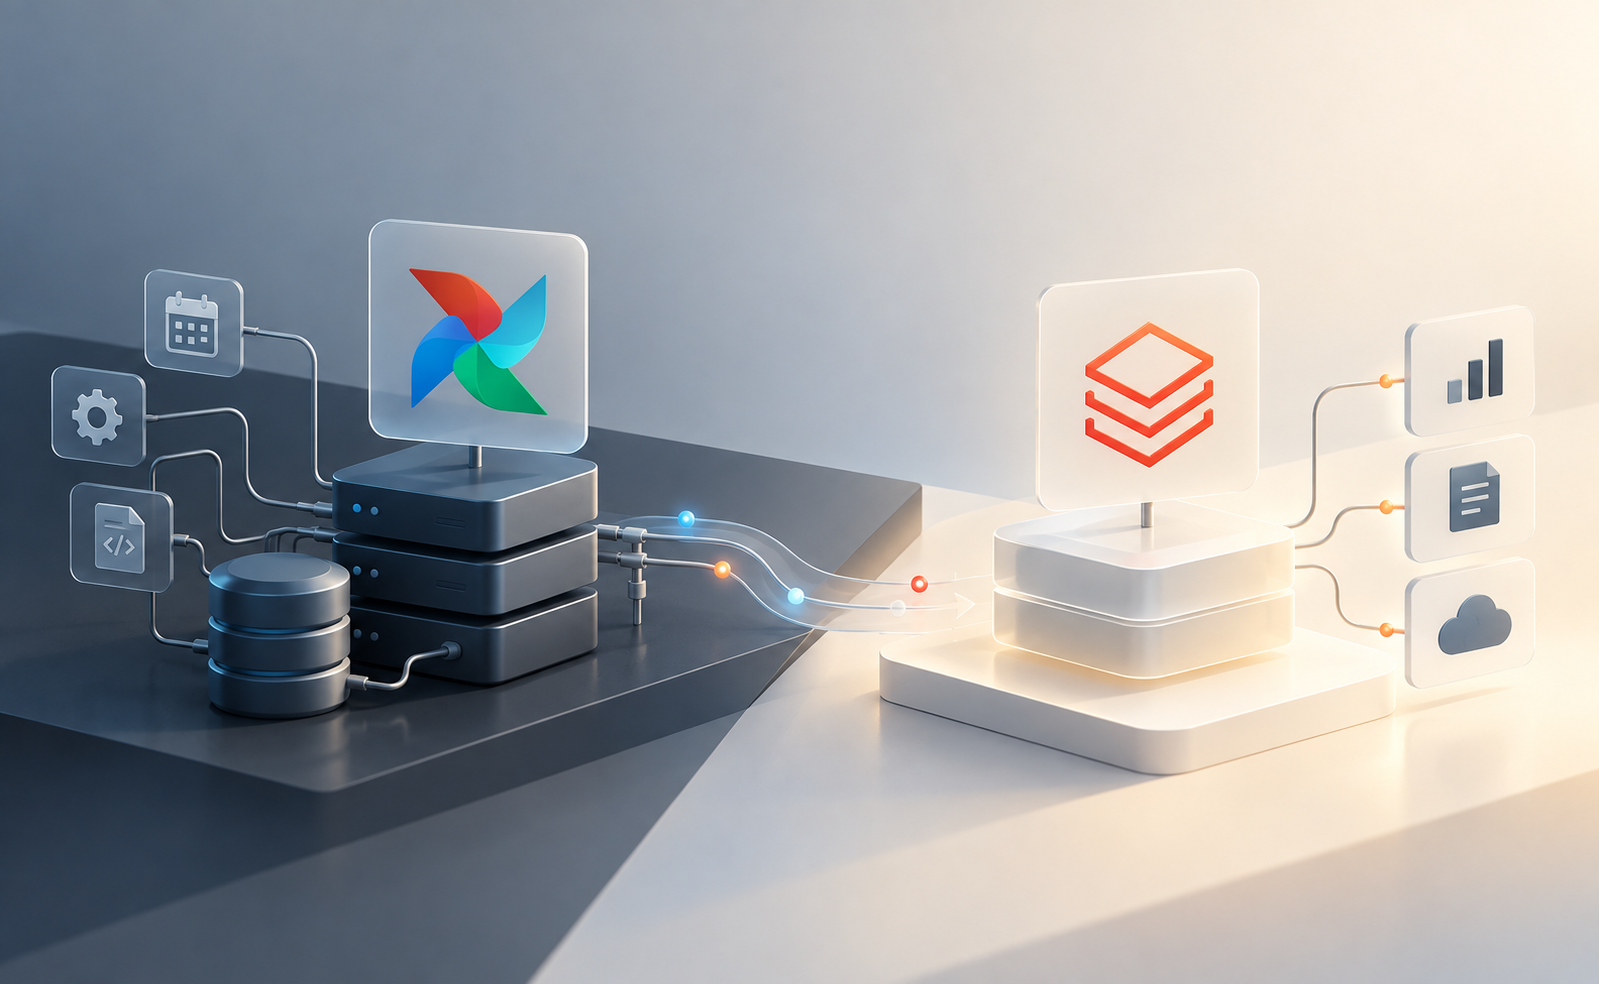
Traditional vs Lakeflow
Ideal for Every Use Case
The visual on the page also presents Lakeflow as applicable across multiple use cases, including:
How Lakeflow Helps Data Teams
Move faster
Standardize ingestion and transformation patterns so teams spend less time rebuilding pipelines.
Improve trust
Apply expectations and quality checks early, making downstream data more dependable.
Reduce operations
Use managed orchestration and serverless compute to reduce infrastructure work.
Prepare for AI
Deliver governed, fresh and business-ready data to ML, RAG and AI applications.
Designing a Production-Ready Lakeflow Platform
- 01Connect the right sources and establish incremental ingestion.
- 02Apply validation and business rules close to the data.
- 03Structure Bronze, Silver and Gold datasets for clear ownership.
- 04Orchestrate dependencies, alerts and refresh cycles.
- 05Expose trusted data through analytics, ML and AI services.
Lakehouse + Governance + AI
- ✓Lakeflow centralizes the movement and transformation of data.
- ✓Delta Lake provides reliable, transactional storage for trusted datasets.
- ✓Unity Catalog supports governance, discovery, access control and lineage.
- ✓Analytics, ML, RAG and AI applications can consume the same governed foundation.
Closing
Build intelligent pipelines. Deliver trusted data. Power AI.
Abilytics helps enterprises modernize their data platforms with Databricks Lakeflow.